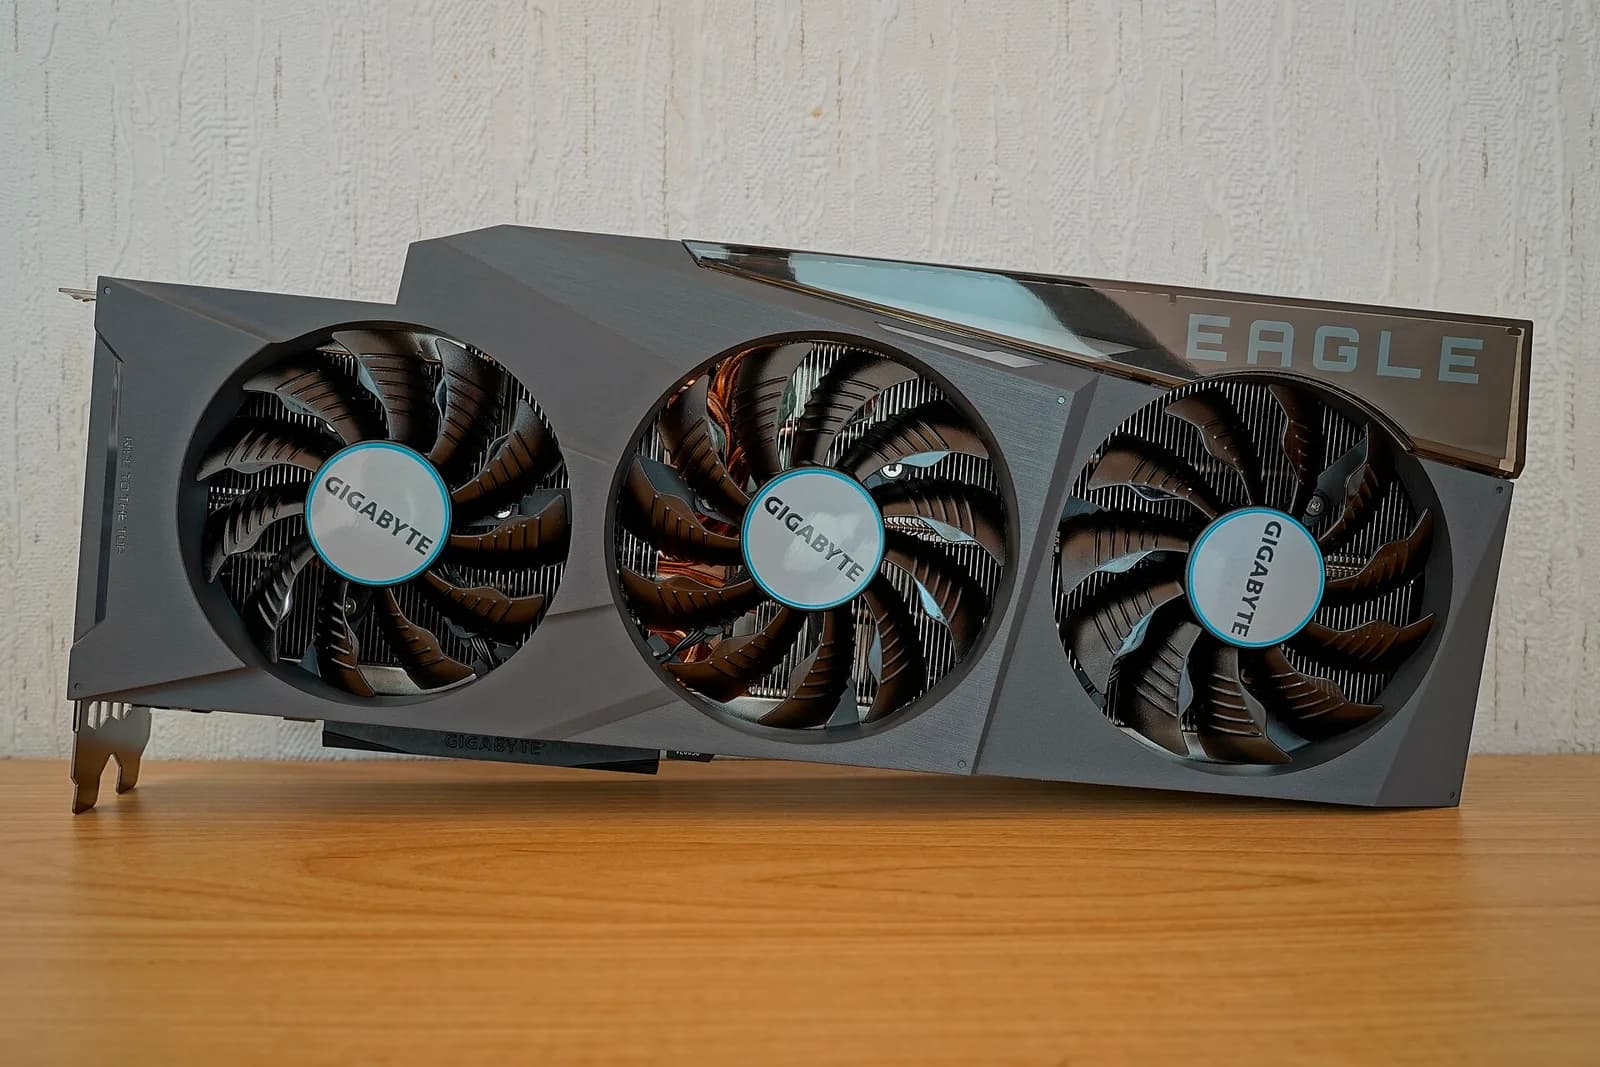
Nvidia's RTX 3090 was released on 24 September 2020, with a launch price of $1,499. The BFGPU was a replacement for the Titan and of little use to most gamers. Six years later, the median used price in our data had risen to $1,395 in October 2026 from $720 the December before. For a 24 GB build, it would still be our starting point. It offers about 93% of an RTX 4090's estimated text generation speed, for half the used price. The 4090 pulls clearly ahead only when it has long prompts to read, and the cheaper RX 7900 XTX makes sense if you already run AMD's ROCm on Linux.
Key takeaways
- The 3090 offers the same models and about 93% of the estimated speed of a 4090, for half the used price.
- For a 4,000-token prompt, we estimate about 3 seconds before the 4090 starts answering, against about 7 for the 3090.
- Two 3090s hold a 70B model at Q4_K_M only with a short context. With a 16K context we estimate Llama 3.3 70B at Q4_K_M needs 51.3 GB.
- The used price has nearly doubled in ten months. A guide that quotes a $700 card is a year out of date.
A Titan for people who don't play games
In its launch post, Nvidia called the 3090 "our big ferocious GPU, or 'BFGPU'". It was "great for creators", "sure to appeal to researchers" and "ideal for extreme gamers who want to experience the new world of 8K gaming". The post also said: "we want to apologise upfront that this will be in limited supply on launch day." Most reviewers judged it as a gaming card, which it barely was. Tom's Hardware headlined its review as "Heir to the Titan Throne", and that was the right frame. ServeTheHome reviewed the card for compute work that December and pointed out that "the Titan RTX is a $2,500 card while the newer larger RTX 3090 is $1,500", with the same 24 GB of memory. Igor's Lab called it "a nice piece of technology at a quite self-confident price". At the time of writing, in late 2026, used prices are about that same self-confident price.
Tom's Hardware noted: "The extra VRAM doesn't really matter much for most games". For local models, that memory is exactly what is needed. In order to generate text quickly, a model's weights need to be stored in GPU memory. Since each token reads all of a dense model's weights, memory bandwidth determines the generation speed. Memory capacity determines what will run. The 3090 has 24 GB of GDDR6X memory with a bandwidth of 936 GB/s. It was succeeded in 2022 by the 4090, which kept the 24 GB and had about 8% more bandwidth. No GeForce card had more memory until the RTX 5090 in 2025.
A 2020 gaming flagship whose 24 GB still sets the bar for local models
What 24 GB holds in 2026
By our Score, the best model that fits a single 24 GB card is Qwen3.8 27B. For Q4_K_M with a 16K-token context, our estimated memory use is 17.9 GB and about 6 GB is free for an increase to 64K before the card fills up.
| # | Model | Speed on RTX 3090 | llmrun Score | Quant · VRAM |
|---|---|---|---|---|
| 1 | Qwen3.8 27BAlibabaHow to run → Q4_K_M · 17.9 GB · 34.9 t/s | 34.9 tok/s | Q4_K_M · 17.9 GB | |
| 2 | Qwen3.6 27BAlibaba Q4_K_M · 17.9 GB · 34.9 t/s | 34.9 tok/s | Q4_K_M · 17.9 GB | |
| 3 | Gemma 4 31B ITGoogle Q4_K_M · 21.7 GB · 29.8 t/s | 29.8 tok/s | Q4_K_M · 21.7 GB | |
| 4 | Gemma 4 26B A4B ITGoogle Q4_K_M · 16.5 GB · 162 t/s | 162 tok/s | Q4_K_M · 16.5 GB |
The rest of this review judges the card's performance on the 27B. The largest model we rate as running well on a 3090 is the mixture-of-experts Qwen3.6 35B A3B (22 GB), which leaves little room for context. See our breakdown of Qwen3.8 27B's memory for every quant from 8K to 64K, and the 24 GB tier page for everything that fits.
How fast it feels
The 3090 is nearly as fast as the 4090 at writing text, by our estimate. Our estimated speed for the 3090 on Qwen3.8 27B is about 35 tok/s. At an average adult non-fiction reading speed of about 238 words a minute, roughly four words a second, the card prints a reply several times faster than anyone can read it. Hardware Corner recorded 33.5 tok/s on a 3090 with Qwen3.5 27B at 4-bit, in line with our figure.
- RTX 3090
- RTX 4090
Qwen3.5 9B
RTX 309095.7RTX 4090103Qwen3 14B
RTX 309064.1RTX 409069Qwen3.8 27B
RTX 309034.9RTX 409037.6Qwen3.6 35B A3B (MoE)
RTX 3090143.6RTX 4090151
| Item | RTX 3090 | RTX 4090 |
|---|---|---|
| Qwen3.5 9B | 95.7 | 103 |
| Qwen3 14B | 64.1 | 69 |
| Qwen3.8 27B | 34.9 | 37.6 |
| Qwen3.6 35B A3B (MoE) | 143.6 | 151 |
Start with the bottom pair. By our estimate, the mixture-of-experts model runs about four times faster than the dense 27B on both cards, because it reads only about 3 billion parameters for each token (why MoE models decode faster).
Prompt processing is where the difference lies. All of your input must be processed before the first word of the answer, with more dependence on raw compute than on memory speed. The difference will pass unnoticed in a chat. Paste a long file into a coding agent and starting the 27B's reply to a 4,000-token prompt takes about seven seconds for the 3090 and about three for the 4090, by our estimate.
- RTX 40901,338
- RTX 3090577
- RX 7900 XTX486
| Item | prompt processing, tok/s, estimated, Qwen3.8 27B Q4_K_M |
|---|---|
| RTX 4090 | 1,338 |
| RTX 3090 | 577 |
| RX 7900 XTX | 486 |
We can be more confident about the ratio. With a 7B model, llama.cpp's public CUDA scoreboard puts the 4090 at 2.3 times the 3090's prompt reading speed, matching our estimated gap. Hardware Corner reported prompt reading at about 1,100 tok/s on a 3090 with a 27B Qwen, close to twice our cautious estimate. That would bring the wait nearer four seconds. Agents send prompts that long on every turn, including with the best open models for agentic coding at 24 GB.
What six years do to a card
Half of the 3090's memory is stored on the back of the card. In its teardown, Igor's Lab found 24 one-gigabyte GDDR6X chips, twelve on each side of the board. NVIDIA "thermally connects … the memory … to the backplate", according to the review, and the backplate is all that cools the rear twelve. The chips ran hot even when new. Tom's Hardware tested a Founders Edition in Cyberpunk 2077, and "GDDR6X temperatures for that card peaked at 100C." With Ethereum mining, the chips reached 110 °C and "the GPU would downclock itself severely" to protect them.
Thermal pads deteriorate over time, so memory temperature is worth checking on a used card. HWiNFO64 on Windows lists it as "GDDR6X Memory Junction Temperature". For GeForce cards on Linux, nvidia-smi does not report it. Open-source readers such as gddr6 use undocumented registers and require root. Notebookcheck reported in 2021 that a Founders Edition's memory had reached about 110 °C before a pad swap, and that after it the card was "sitting at approximately 85 °C".
Many used 3090s spent their first two years mining Ethereum, which stopped using GPUs on 15 September 2022. We have no failure-rate data for ex-mining cards. Fans and pads wear out with use, whatever the hours were spent on, so checking the temperature tells more than a seller's story of where the card came from.
One other thing to consider is power. The card is rated at 350 W, and the recommended power supply is 750 W (NVIDIA). Igor's Lab warned at launch that peaks lasting 1 to 10 milliseconds "can lead to shutdowns in very fast reacting protective circuits", and within a week a Linus Tech Tips forum summary was collecting reports of power supplies shutting down under new 3080s and 3090s. Fortunately, text generation has little use for the full power budget. On llama.cpp's scoreboard, one owner capped their 3090 at 250 W and lost about 9% of generation speed against the card's 390 W default.
Two cards and a bridge that got rare
The 3090 and 3090 Ti are the last GeForce cards to support NVLink. Nvidia dropped support for NVLink in Ada. As Jensen Huang explained in 2022, "we needed the I/Os for something else." With two 3090s there is 48 GB in total, and that is the usual way to run a 70B model at home on CUDA.
For running models, the bridge is optional. In llama.cpp, the default split is by layer, described as "split layers … across GPUs", and vLLM's documentation says that "if the GPUs on the node do not have NVLINK interconnect … leverage pipeline parallelism". "You really don't need NVLink, you won't saturate the PCIe lanes on a modern motherboard with dual 3090s," one Hacker News commenter wrote in a 2025 thread about a dual-3090 rig. That is fortunate, as 30-series bridges have since become very hard to find on the used market. Each card is three slots thick, so choosing a board and case with room between the cards matters more than the bridge.
Whether a 70B model will fit depends on the context. Our estimate for Llama 3.3 70B at Q4_K_M is 51.3 GB with the 16K-token context we use for every fit, which is more than the pair can hold. With about 4,000 tokens of context, the estimated requirement of 47.2 GB is just within the limits of the pair. Owners run the model with a short context. XiongjieDai's public benchmarks measured Llama 3 70B Q4_K_M on two 3090s at a speed of about 16 tok/s in llama.cpp. At an estimated 46.4 GB, the 4-bit IQ4_XS is the quant that fits with the full 16K. We make no estimates of multi-GPU speed.
The rivals: a faster 4090, a cheaper 7900 XTX
The 3090 and the RX 7900 XTX cost about the same per token and the 4090 costs close to twice as much. These costs are worked out by dividing each card's used price plus three years of electricity by what it would generate on Qwen3.8 27B at four hours a day.
| Hardware | Price | Speed | Power W | $ per 1M tokens |
|---|---|---|---|---|
| RTX 3090 | $1,500used · Oct 13 | 35 | 350 (best) | $3.13 |
| RTX 4090 | $3,000used · Oct 13 | 38 (best) | 450 | $5.50 |
| RX 7900 XTX | $1,200used · Nov 14 (best) | 33 | 355 | $2.75 (best) |
- RTX 3090$1,500used
- RTX 4090$3,000used
- RX 7900 XTX$1,200used
- USD · lower is better
- RTX 3090350
- RTX 4090450
- RX 7900 XTX355
- W · lower is better
- RTX 3090$3.13
- RTX 4090$5.50
- RX 7900 XTX$2.75
- USD per 1M tokens · lower is better
The 7900 XTX is a few percent slower than the 3090 on every model we estimate. That is too little to feel; the choice depends on which software you are using. AMD supports ROCm only on specific Ubuntu and RHEL releases. As our AMD and Intel guide explains for the setups AMD actually documents, software that expects CUDA needs a different stack. We would recommend the 7900 XTX only if you already run a Linux release supported by ROCm.
The electricity cost makes very little difference. Based on four hours a day at its full 350 W and $0.15 per kWh, a 3090 would run up an electricity bill of about $77 a year, with a 4090 about $22 more. The 4090 is a better card apart from the price, but it is only with days full of long prompts that its advantage saves time.
The price went the wrong way
The monthly median used 3090 price in our data for last December was $720. By October 2026, that was $1,395, about $100 below Nvidia's price for a new one in 2020. In the same months, prices of the used 7900 XTX went from $697 to $1,020 and the used 4090 from $2,422 to $3,167. In our single-day data, the used prices were about $1,500 for the 3090 and $3,000 for the 4090 (both observed 2026-10-13).
- Used, Oct 2026
- $1,395
- Used, Dec 2025
- $720
- Launch price (MSRP)
- $1,499
| Month | New | Used |
|---|---|---|
| Dec 2025 | — | $720 |
| Jan 2026 | — | $813 |
| Feb 2026 | — | $873 |
| Mar 2026 | — | $1,017 |
| Apr 2026 | — | $1,096 |
| May 2026 | — | $983 |
| Jun 2026 | — | $1,164 |
| Jul 2026 | — | $1,158 |
| Aug 2026 | — | $1,182 |
| Sep 2026 | — | $1,380 |
| Oct 2026 | — | $1,395 |
Our data cannot explain the rise. Alongside it is a memory shortage driven by AI data centres; TechRadar, citing Counterpoint, reports DRAM revenue in the third quarter of 2026 up 369% year on year, "with a price surge doing most of the work". A guide quoting a $700 used 3090 has last winter's price, whatever the cause.
And the 3090 Ti?
Nvidia launched the RTX 3090 Ti refresh in March 2022 for $1,999. Its faster memory matches the 4090's bandwidth at 1,008 GB/s. By our estimate, on Qwen3.8 27B text generation is as fast as a 4090's, but prompt reading is about half as fast. llama.cpp's scoreboard shows the Ti is 8% faster than a 3090 on a 7B. With 2 GB memory chips, TechSpot explained, "there are just 12 modules and they're all on the front side of the PCB". That removes the hot rear memory, and it keeps NVLink. The Ti is rated at 450 W instead of 350 W, and its used price in our data is about $1,600 (2026-10-13).
Verdict
Our choice
We would still choose the 3090 for chat and 27B-class models, since a used 4090 costs about twice as much. Pay for the 4090 for days of long prompts; choose the 7900 XTX only if you already run a Linux release supported by ROCm.
Good for
- For chat and 27B-class models on CUDA
- For starting with 24 GB and adding a second card
- For buyers prepared to check a used card's memory temperature before relying on it
Not for
- All-day agent users: we estimate the 4090 reads prompts more than twice as fast
- Anyone needing a warranty: these prices are for used cards
- Readers needing Llama 3.3 70B Q4_K_M at 16K: our memory estimate exceeds the pair's capacity